I'm a PhD student at the Institute for Machine Learning at ETH Zürich, where I'm advised by Prof. Ryan Cotterell at Rycolab.
Before that, I studied data science at ETH Zürich, graduating with a thesis on controlled LLM code generation at IBM Research.
My research focuses on how language models learn from limited evidence, particularly how they infer latent rules and intentions from user interactions.
I take an interdisciplinary approach, drawing on probabilistic inference and HCI.
My goal is to build language modeling systems that reason with calibrated uncertainty and collaborate with people to solve tasks.
I make an effort to engage broadly with the ML, NLP, and HCI research communities.
I'm quite active in the GenLM research consortium, where we are building an open-source ecosystem for language model probabilistic programming.
Beyond that, I co-organize workshops and conference tutorials,
and review regularly for NeurIPS/ICML/ICLR and CHI/IUI/UIST.
New preprint on arXiv about interactive program induction with LMs!
Our paper on ensembling language models with SMC was accepted to NeurIPS'26—see you in Sydney!
The ensembling code has also been merged into genlm/genlm-control.
We won a best paper award at CHI'26 (top 1% of main conference submissions)! 🏆 Our work was also featured on the ETH Zürich departmental news.
I got outstanding reviewer awards at NeurIPS and ICML 🏆
We just published a new preprint about ensembling language models with sequential Monte Carlo with the people at GenLM!
One paper about interactive ambiguity resolution in natural language interfaces was accepted to CHI 2026.
Thanks to the team; preprint available here! We also released an
interactive blog post about it.
One paper accepted to IEEE VIS 2025 in Vienna — congratulations to the team!
Our paper Finding Needles in Document Haystacks: Augmenting Serendipitous Claim Retrieval Workflows was accepted to CHI 2025 in Yokohama, Japan — congratulations to the team!
Our paper A Design Space for Intelligent Dialogue Augmentation was accepted to ACM IUI 2025! I will be presenting it in Cagliari in March. Thanks to all co-authors!
The paper we wrote at IBM Research on API integration with LLMs was accepted to EMNLP 2024 (Industry Track) — thanks to all co-authors! My colleague Thomas Gschwind from IBM Research will be presenting it in Miami in November.
Our paper On Affine Homotopy between Language Encoders was accepted to NeurIPS 2024. I will be presenting it in Vancouver in December. Thanks to all co-authors!
We gave a tutorial about the representational capacity of neural language models at ACL 2024 in Bangkok. Check out the tutorial paper!
Two papers I co-authored were accepted to ACL 2024!
Started a PhD at ETH Zürich, co-advised by Prof. Menna El-Assady and Prof. Ryan Cotterell! 🎉
Together with Katya Mirylenka, we will give a talk at Zurich-NLP about our work at IBM Research, at the ETH AI Center. RSVP here!
Our paper on counterfactual sample generation was accepted to ACL. I will be presenting it in Toronto in a few days! Check out our blog post about the paper!
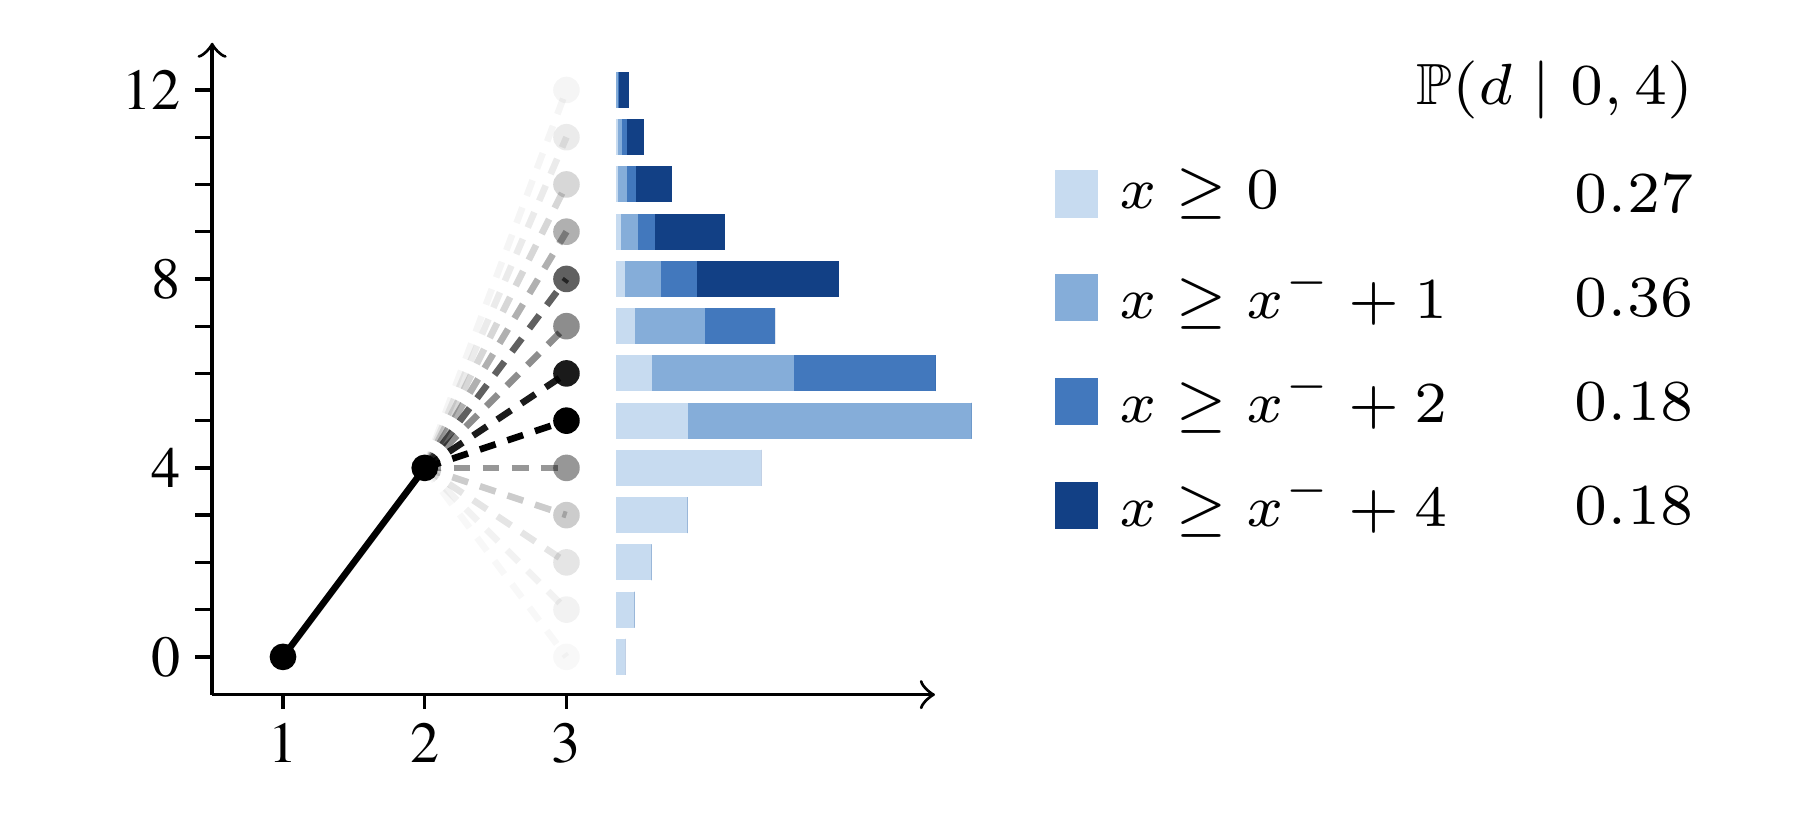
Program induction refers to the process in which a learner aims to recover a program from a few given input–output examples.
This paradigm broadens programming access by letting users demonstrate the rule-based behavior they want to apply to unseen data, instead of having to implement it themselves.
However, recovering a program from finite input–output examples is fundamentally ambiguous, as a finite set of input–output examples is theoretically consistent with infinitely many programs whose output diverges on unseen inputs.
We view this problem from a Bayesian perspective, where, given a prior p0 over programs, identifying the target program means concentrating posterior probability mass on it by observing additional input–output examples.
In the interactive program induction setting, the learner chooses maximally informative inputs and queries an oracle, such as the user, for their outputs.
We derive a greedy query-selection algorithm and show that it terminates after 𝒪(1⁄γ log 1/p0(f☆)) informative oracle queries, and returns the target program f☆ up to approximate equivalence when no other class outweighs it under the prior.
The algorithm uses a language model as the prior under a PAC-style relaxation of program equivalence, where the query-selection objective is estimated using importance sampling.
On the CodeARC benchmark, the algorithm improves accuracy over the LM only agent by up to 22 percentage points while observing up to 10.5 fewer input–output examples.
Ensembling Language Models with Sequential Monte Carlo
Robin Chan,
Tianyu Liu,
Samuel Kiegeland,
Clemente Pasti,
Jacob Hoover Vigly,
Timothy J. O'Donnell,
Ryan Cotterell,
Tim Vieira
Advances in Neural Information Processing Systems 40 (NeurIPS), 2026 | pdf | code
Abstract
Practitioners have access to an abundance of language models and prompting strategies for solving many language modeling tasks; yet prior work shows that modeling performance is highly sensitive to both choices.
Classical machine learning ensembling techniques offer a principled approach: aggregate predictions from multiple sources to achieve better performance than any single one.
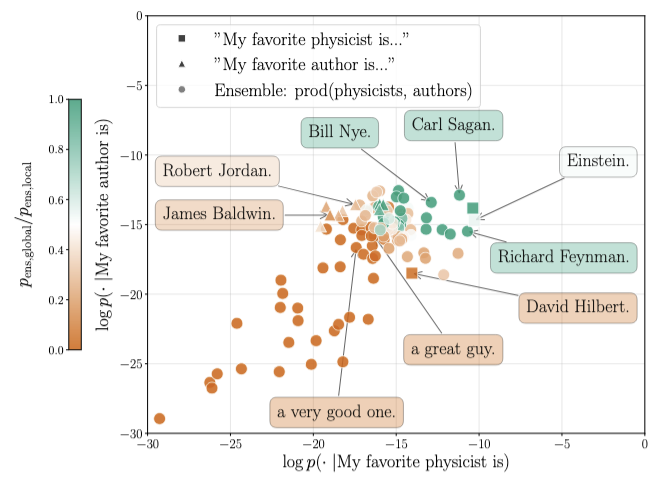
However, applying ensembling to language models during decoding is challenging: naively aggregating next-token probabilities yields samples from a locally normalized, biased approximation of the generally intractable ensemble distribution over strings.
In this work, we introduce a unified framework for composing K language models into f-ensemble distributions for a wide range of functions f: ℝ≥0K → ℝ≥0.
To sample from these distributions, we propose a byte-level sequential Monte Carlo (SMC) algorithm that operates in a shared character space, enabling ensembles of models with mismatching vocabularies and consistent sampling in the limit.
We evaluate a family of f-ensembles across prompt and model combinations for various structured text generation tasks, highlighting the benefits of alternative aggregation strategies over traditional probability averaging, and showing that better posterior approximations can yield better ensemble performance.
PleaSQLarify: Visual Pragmatic Repair for Natural Language Interfaces
Robin Chan,
Rita Sevastjanova,
Menna El-Assady
Proceedings of the ACM CHI Conference on Human Factors in Computing Systems (CHI), 2026 | pdf | code
🏆 Best Paper Award 🏆
Abstract
Natural language database interfaces broaden data access, yet they remain brittle under input ambiguity.
Standard approaches often collapse uncertainty into a single query, offering little support for mismatches between user intent and system interpretation.
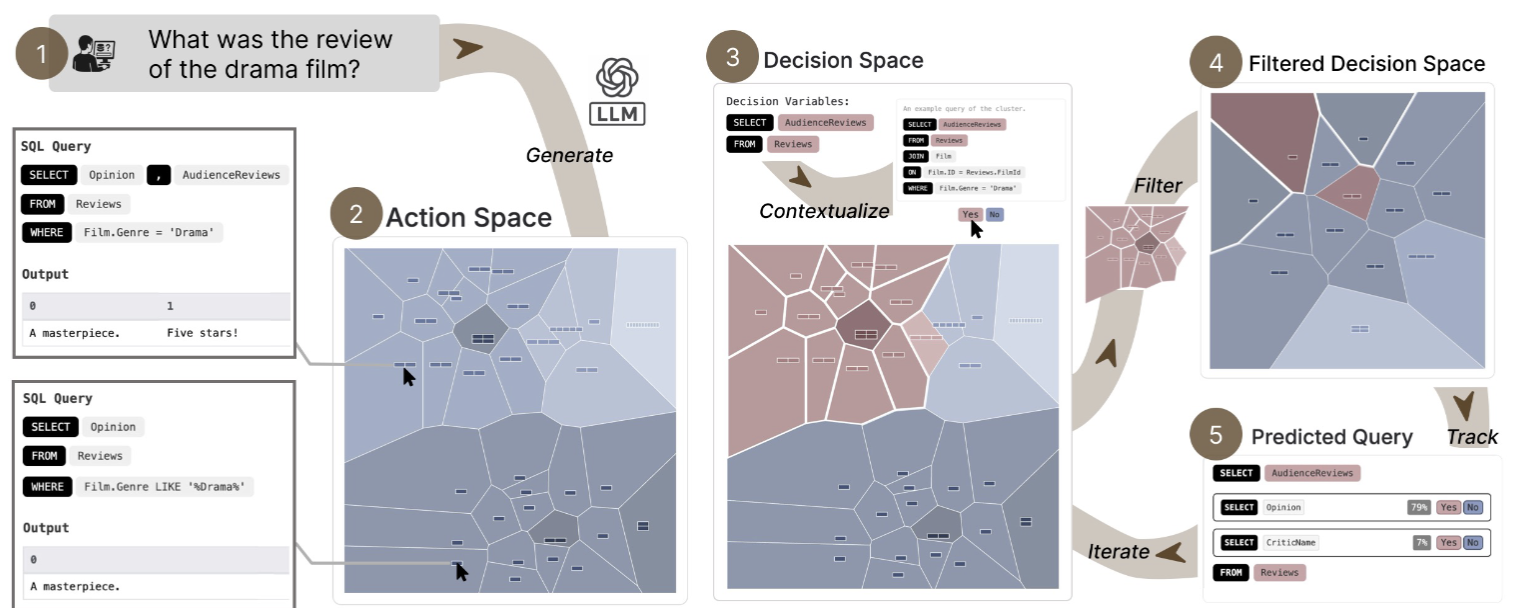
We reframe this challenge through pragmatic inference: while users economize expressions, systems operate on priors over the action space that may not align with the users'.
In this view, pragmatic repair—incremental clarification through minimal interaction—is a natural strategy for resolving underspecification.
We present PleaSQLarify, which operationalizes pragmatic repair by structuring interaction around interpretable decision variables that enable efficient clarification.
A visual interface complements this by surfacing the action space for exploration, requesting user disambiguation, and making belief updates traceable across turns. In a study with twelve participants, PleaSQLarify helped users recognize alternative interpretations and efficiently resolve ambiguity.
Our findings highlight pragmatic repair as a design principle that fosters effective user control in natural language interfaces.
Understanding Large Language Model Behaviors through Interactive Counterfactual Generation and Analysis
Furui Cheng,
Vilém Zouhar,
Robin Chan,
Daniel Fürst,
Hendrik Strobelt,
Menna El-Assady
IEEE Transactions on Visualization and Computer Graphics (IEEE VIS), 2025 | pdf
Abstract
Counterfactual examples are useful for exploring the decision boundaries of machine learning models and determining
feature attributions. How can we apply counterfactual-based methods to analyze and explain LLMs? We identify the following key
challenges. First, the generated textual counterfactuals should be meaningful and readable to users and thus can be mentally compared
to draw conclusions. Second, to make the solution scalable to long-form text, users should be equipped with tools to create batches of
counterfactuals from perturbations at various granularity levels and interactively analyze the results. In this paper, we tackle the above
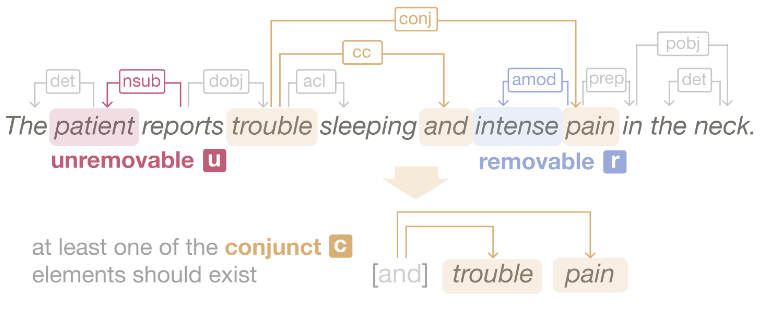
challenges and contribute 1) a novel algorithm for generating batches of complete and meaningful textual counterfactuals by removing
and replacing text segments in different granularities, and 2) LLM Analyzer, an interactive visualization tool to help users understand
an LLM's behaviors by interactively inspecting and aggregating meaningful counterfactuals. We evaluate the proposed algorithm by
the grammatical correctness of its generated counterfactuals using 1,000 samples from medical, legal, finance, education, and news
datasets. In our experiments, 97.2% of the counterfactuals are grammatically correct. Through a use case, user studies, and feedback
from experts, we demonstrate the usefulness and usability of the proposed interactive visualization tool
Which Spurious Correlations Impact Reasoning in NLI Models? A Visual Interactive Diagnosis through Data-Constrained Counterfactuals
Robin Chan,
Afra Amini,
Menna El-Assady
Proceedings of ACL: System Demonstrations, 2023 | pdf | code
Abstract
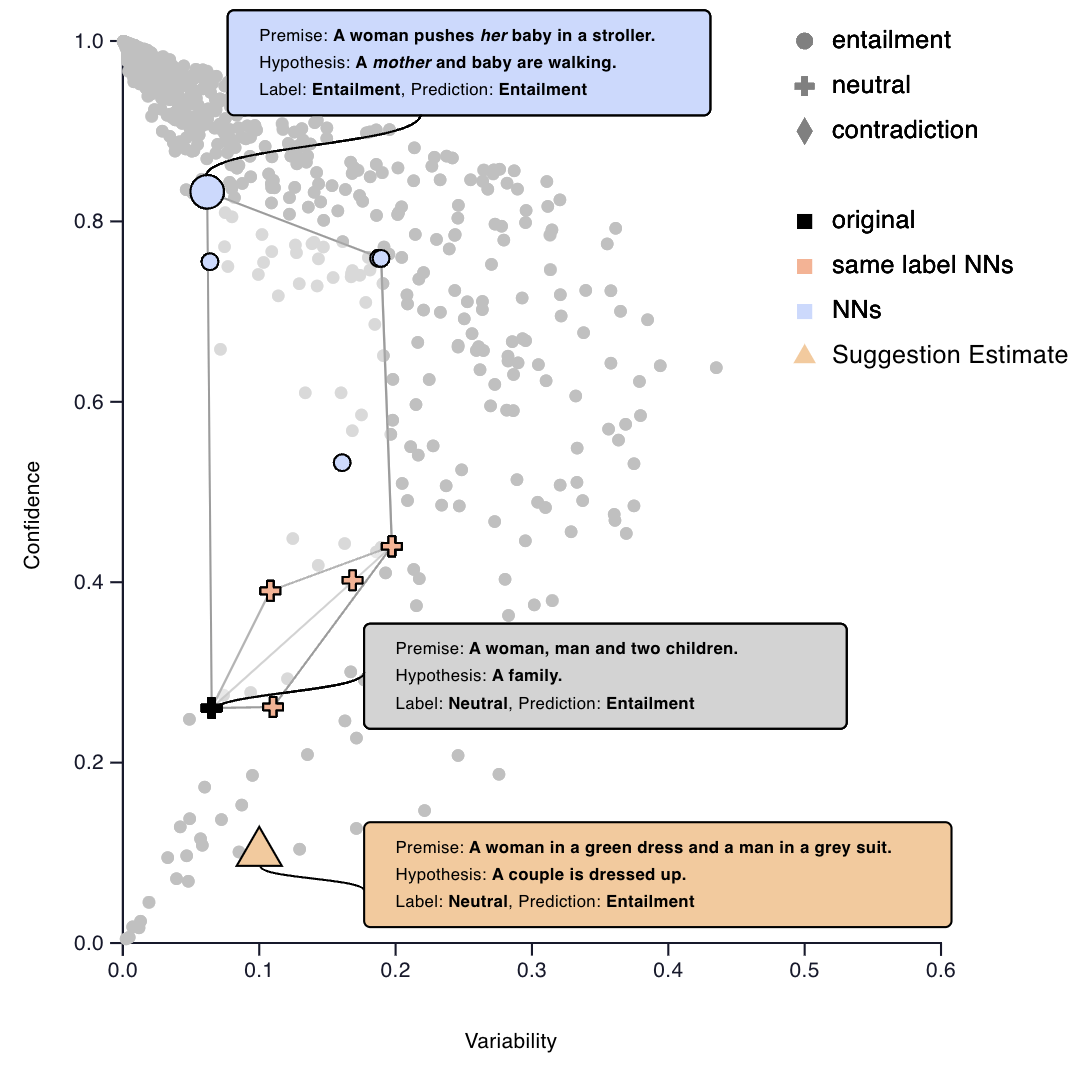
We present a human-in-the-loop dashboard tailored to diagnosing potential spurious features that NLI models rely on for predictions.
The dashboard enables users to generate diverse and challenging examples by drawing inspiration from GPT-3 suggestions.
Additionally, users can receive feedback from a trained NLI model on how challenging the newly created example is and make refinements based on the feedback.
Through our investigation, we discover several categories of spurious correlations that impact the reasoning of NLI models, which we group into three categories:
Semantic Relevance, Logical Fallacies, and Bias. Based on our findings, we identify and describe various research opportunities, including diversifying
training data and assessing NLI models' robustness by creating adversarial test suites.